The AI visibility platform built to win inChatGPT
For marketing teams and agencies that want the work done, not another dashboard. Up to five assistants measured every day, an agent that acts on what they say, from $64/mo billed yearly.
10 buyer questions, 3 assistants, about two minutes — no account needed.
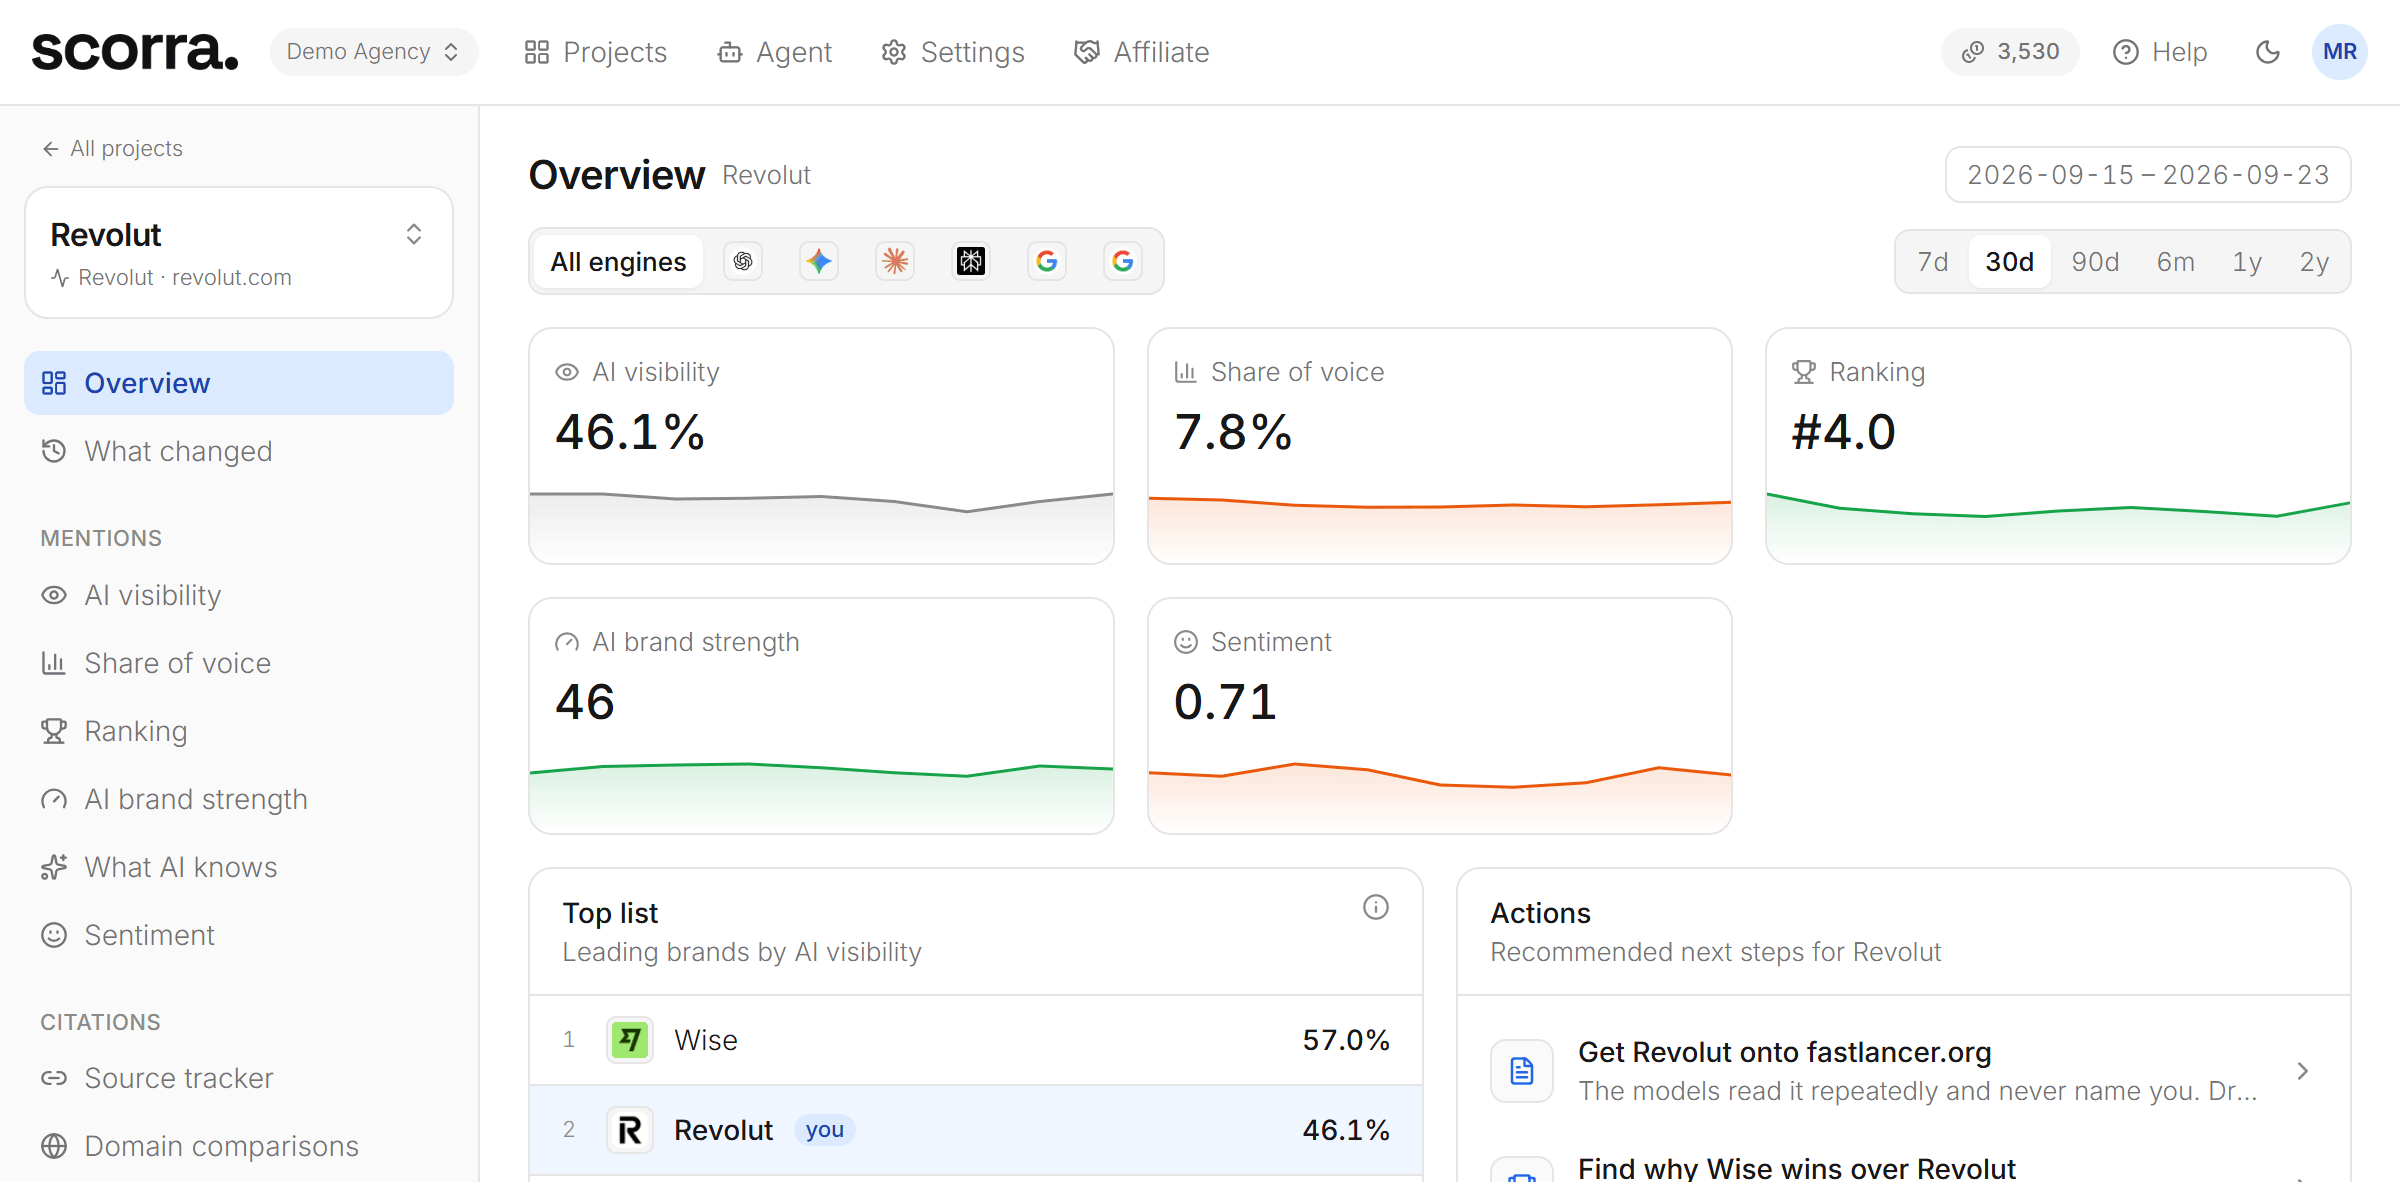
Three numbers that decide whether you get named
Visibility
How often an assistant names you when a buyer asks a question in your category.
Position
Where you land inside the answer — named first, in the top three, or barely there.
Sentiment
How warmly they describe you, with the sentences behind the score.
Ask Claude or ChatGPT. Scorra pulls the numbers.
Plug Scorra into Claude or ChatGPT and ask about your AI visibility the way you would ask a colleague. The answer comes from your own measurements — no dashboard to open, no export to paste.
Included from Growth up. Each tool call uses 1 credit.
Learn more →
See what they read before they answer
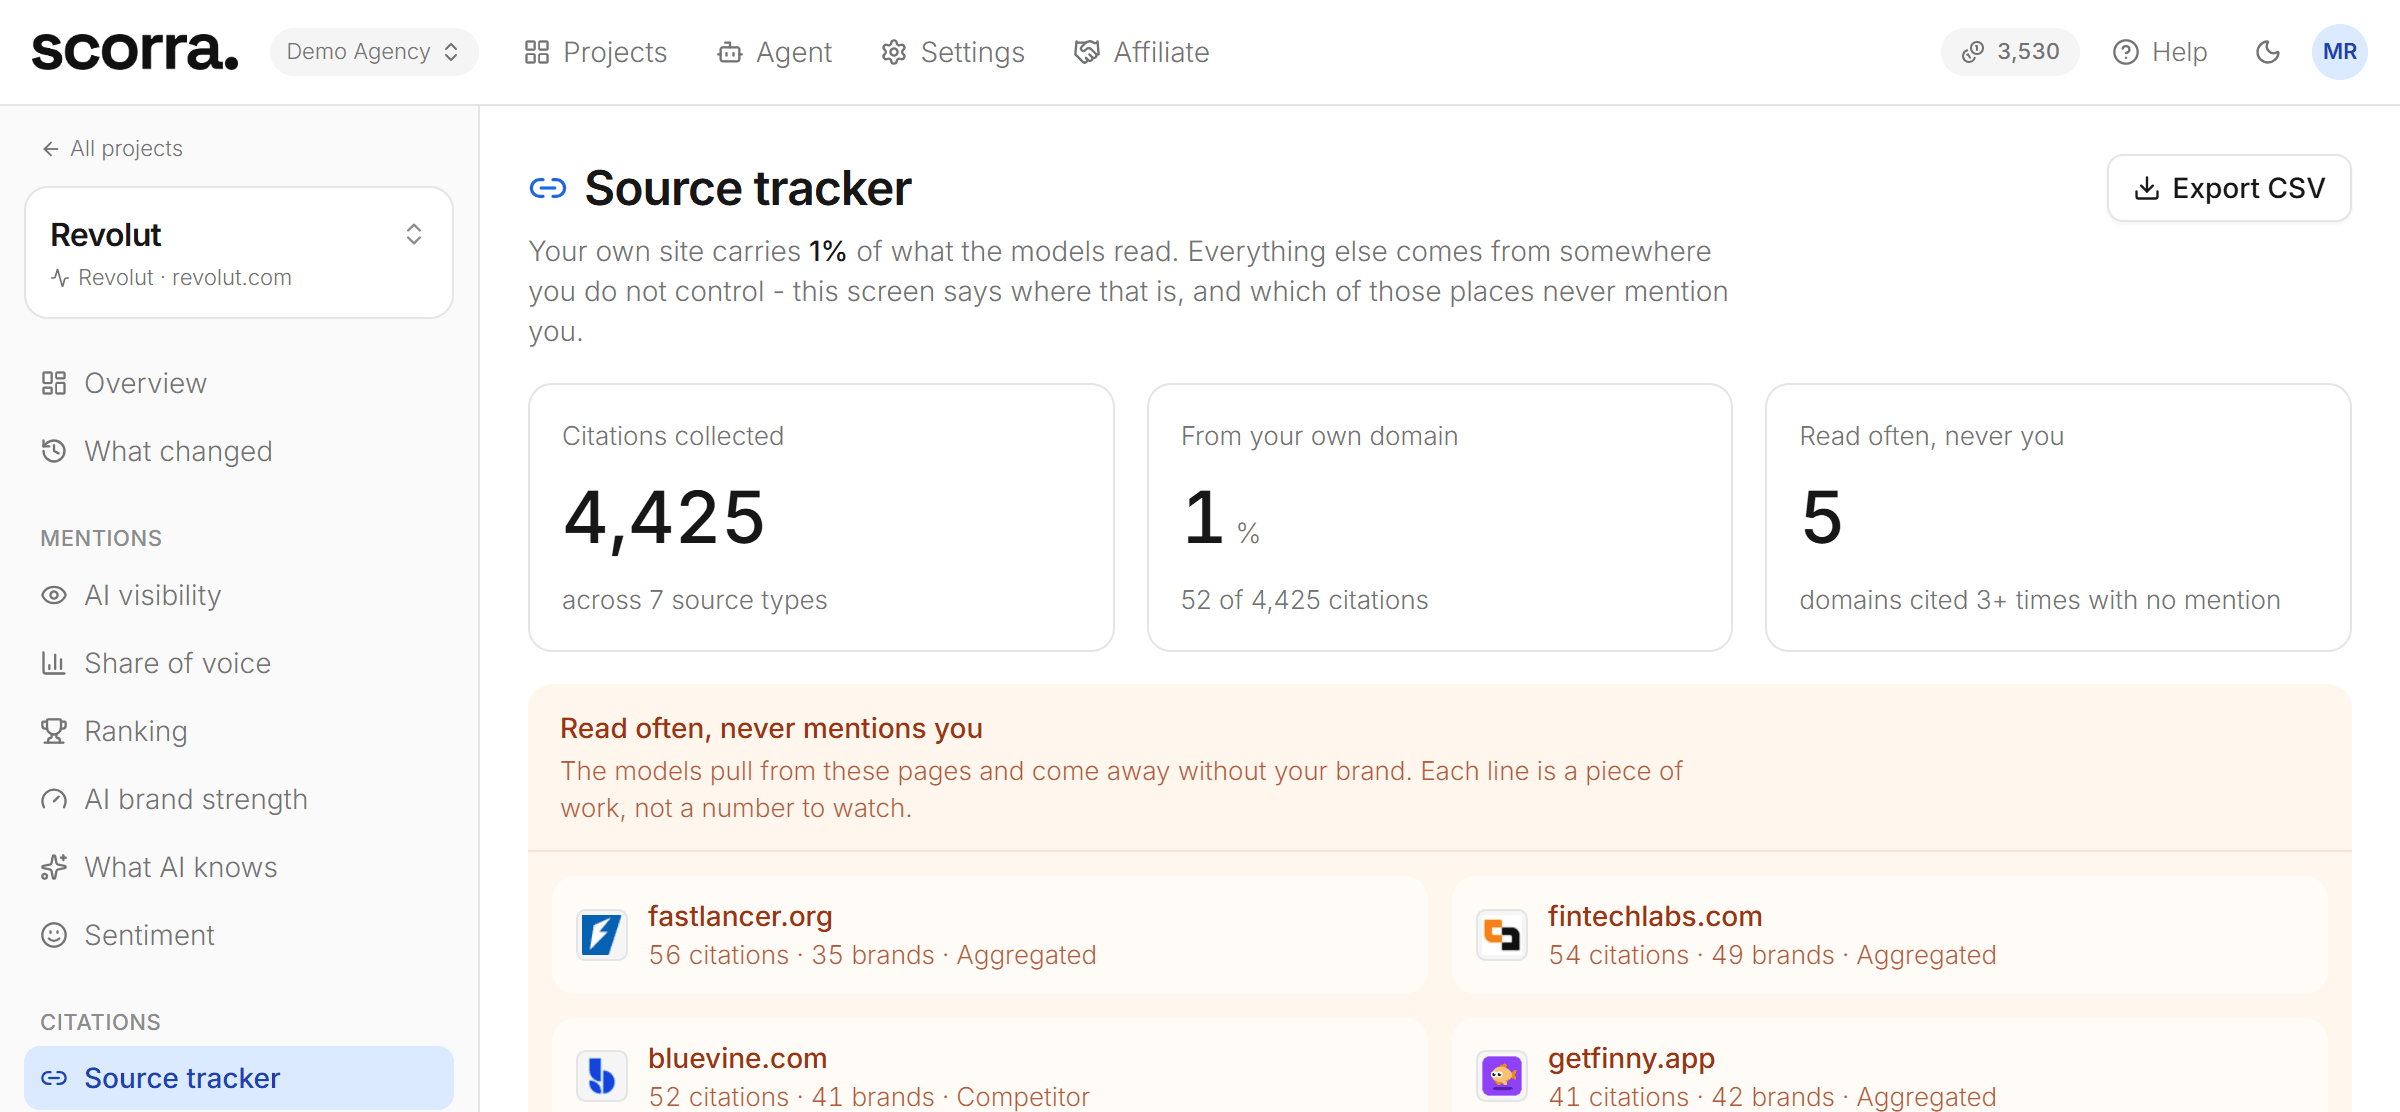
Citation analytics down to the page: every cited domain and URL, sorted into source types and content types, with the questions each one decides — including the five read again and again in answers that never name you.
What you get: A short, ranked list of the publications worth your PR and outreach budget, instead of a guess.
Know who gets named instead of you
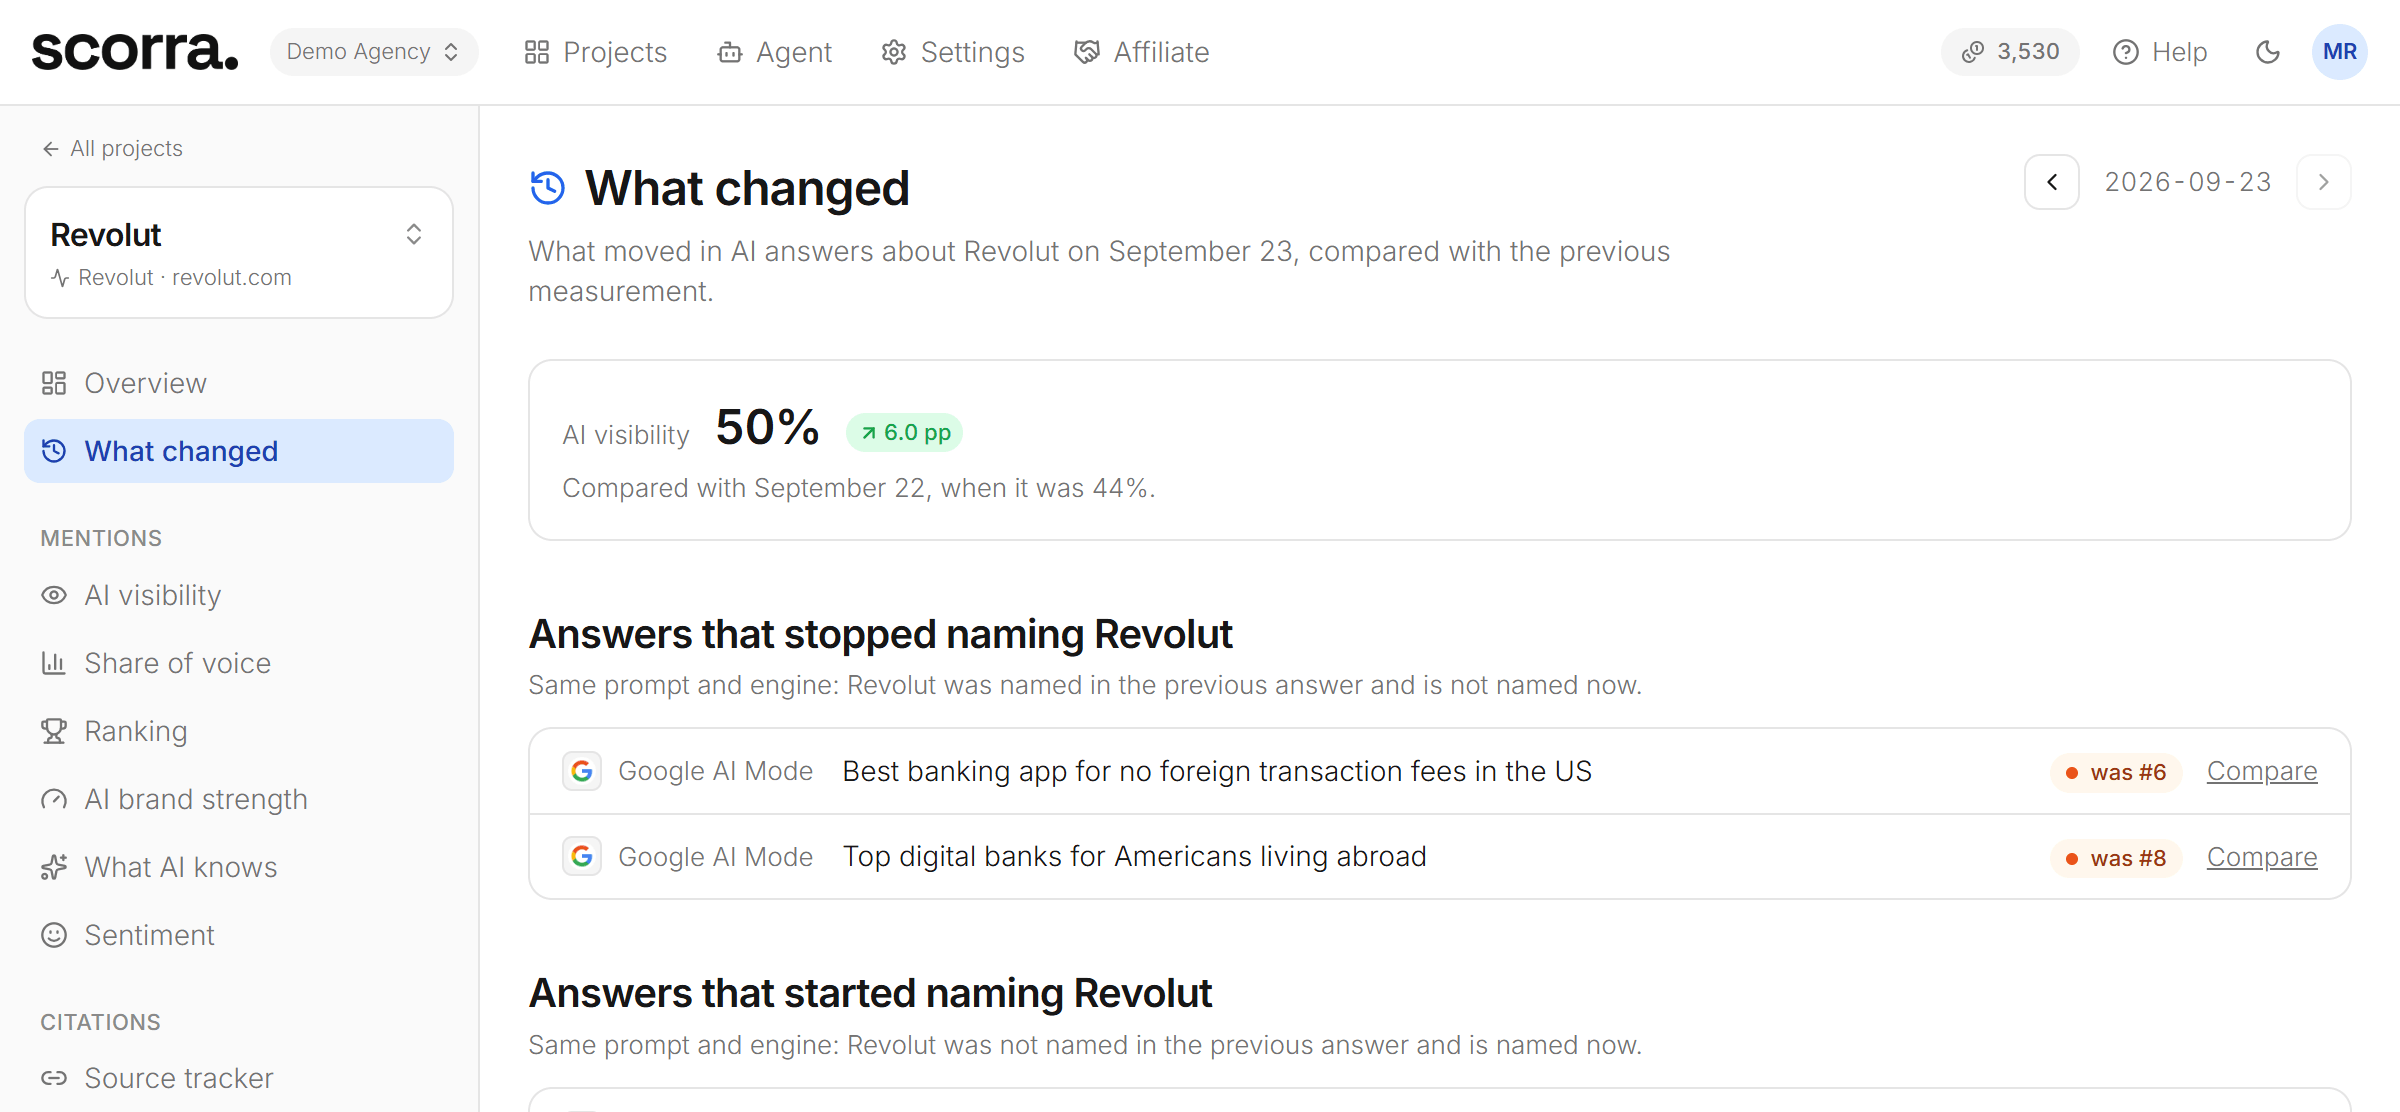
Competitor benchmarking for AI search: visibility, share of voice and average position against every brand in your category, day by day — rivals discovered from the answers themselves.
What you get: You see which competitor is taking the recommendations meant for you, before it shows up as lost deals.
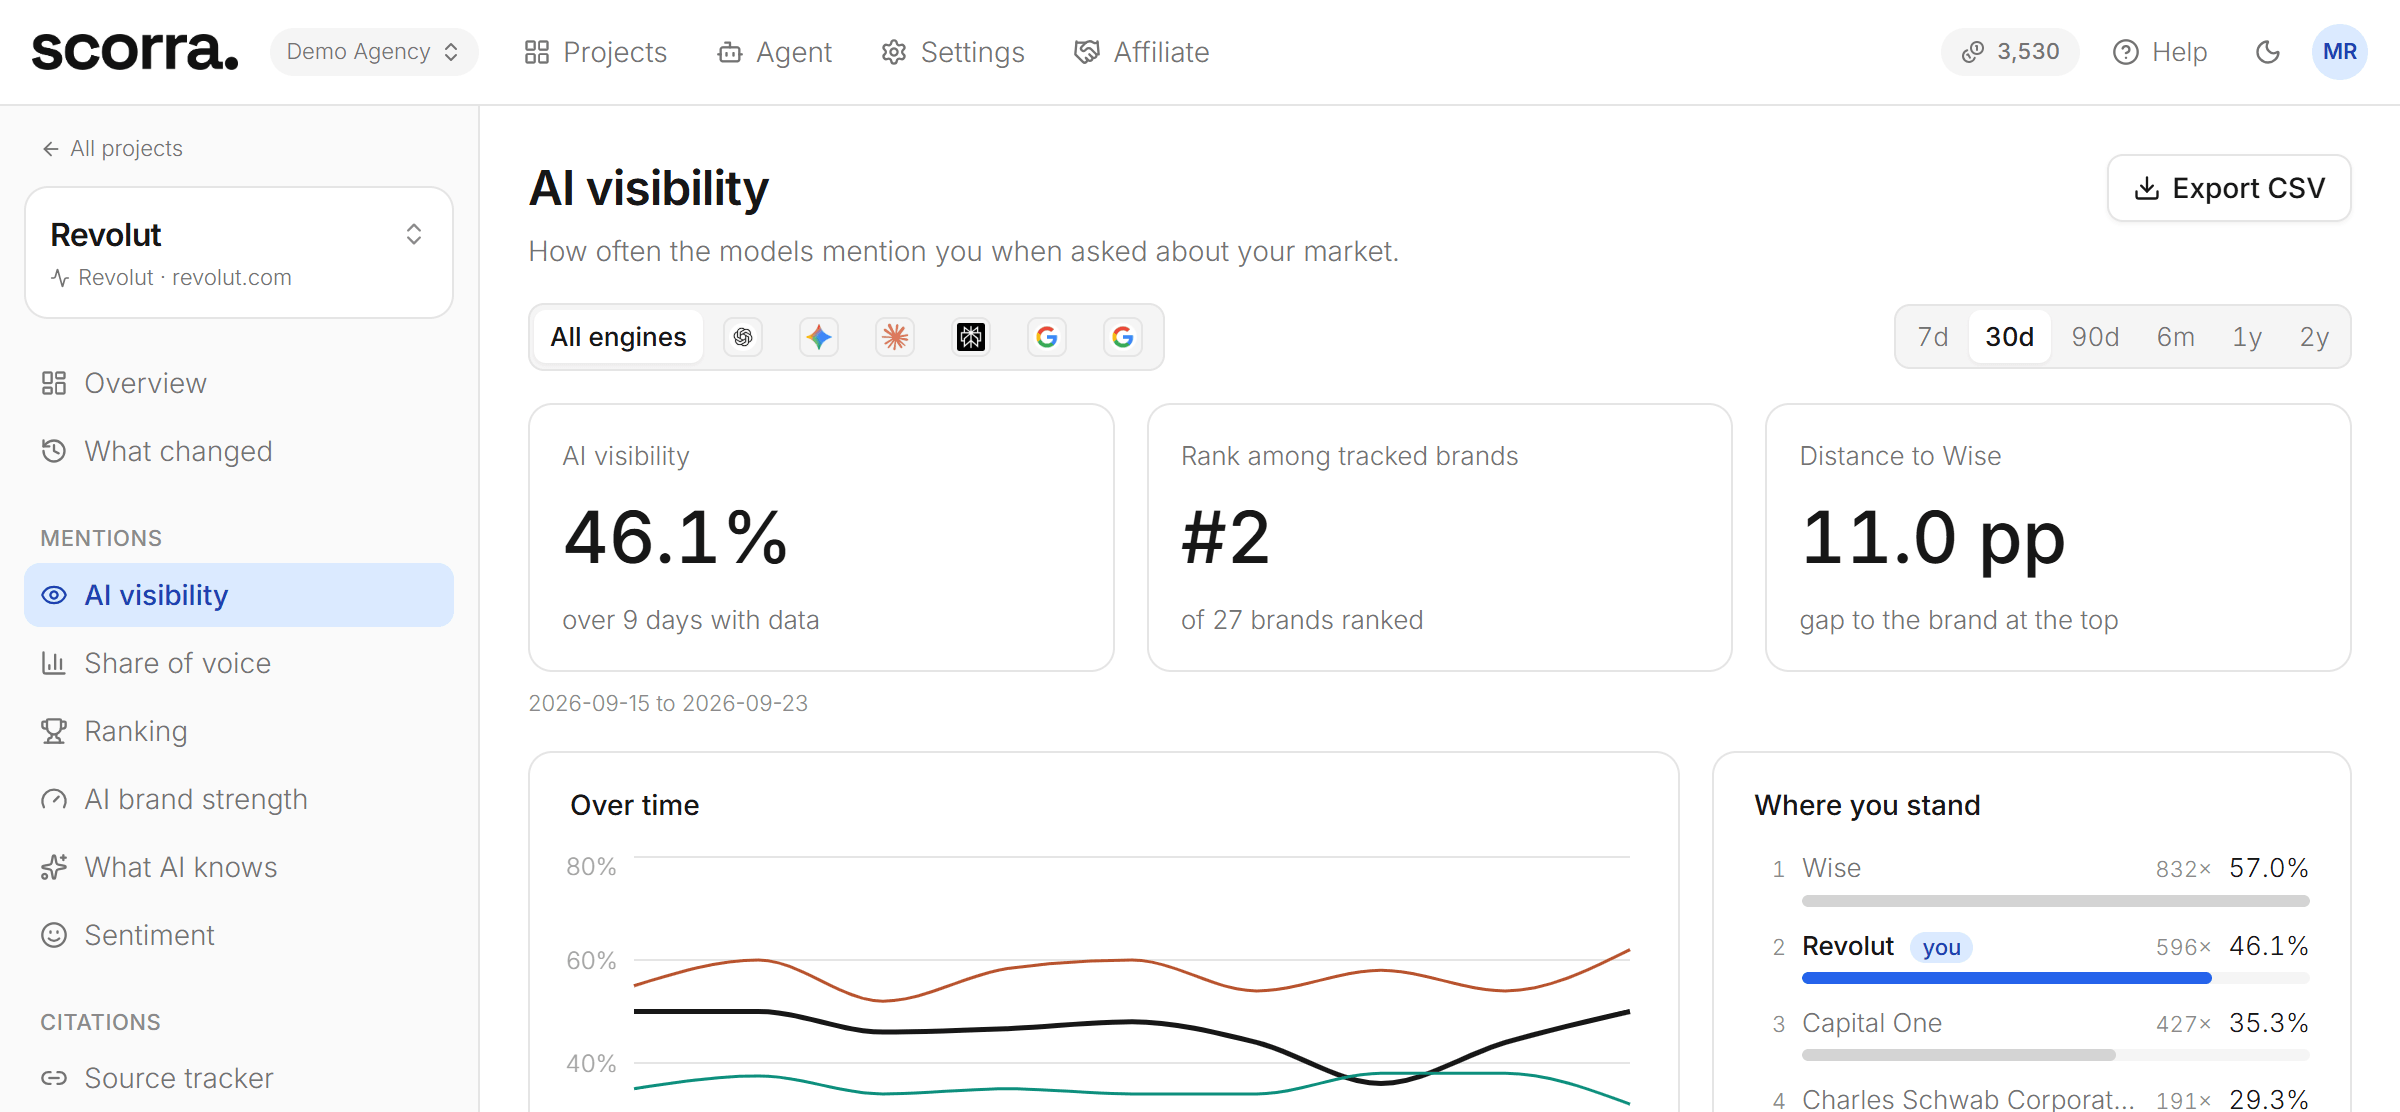
Read the sentences behind the score
Sentiment analysis with the evidence: the passages the models actually wrote, worst first — so you can tell an outdated complaint from one worth answering.
What you get: You fix the old price or the three-year-old review that costs you deals, instead of guessing why the tone is cold.
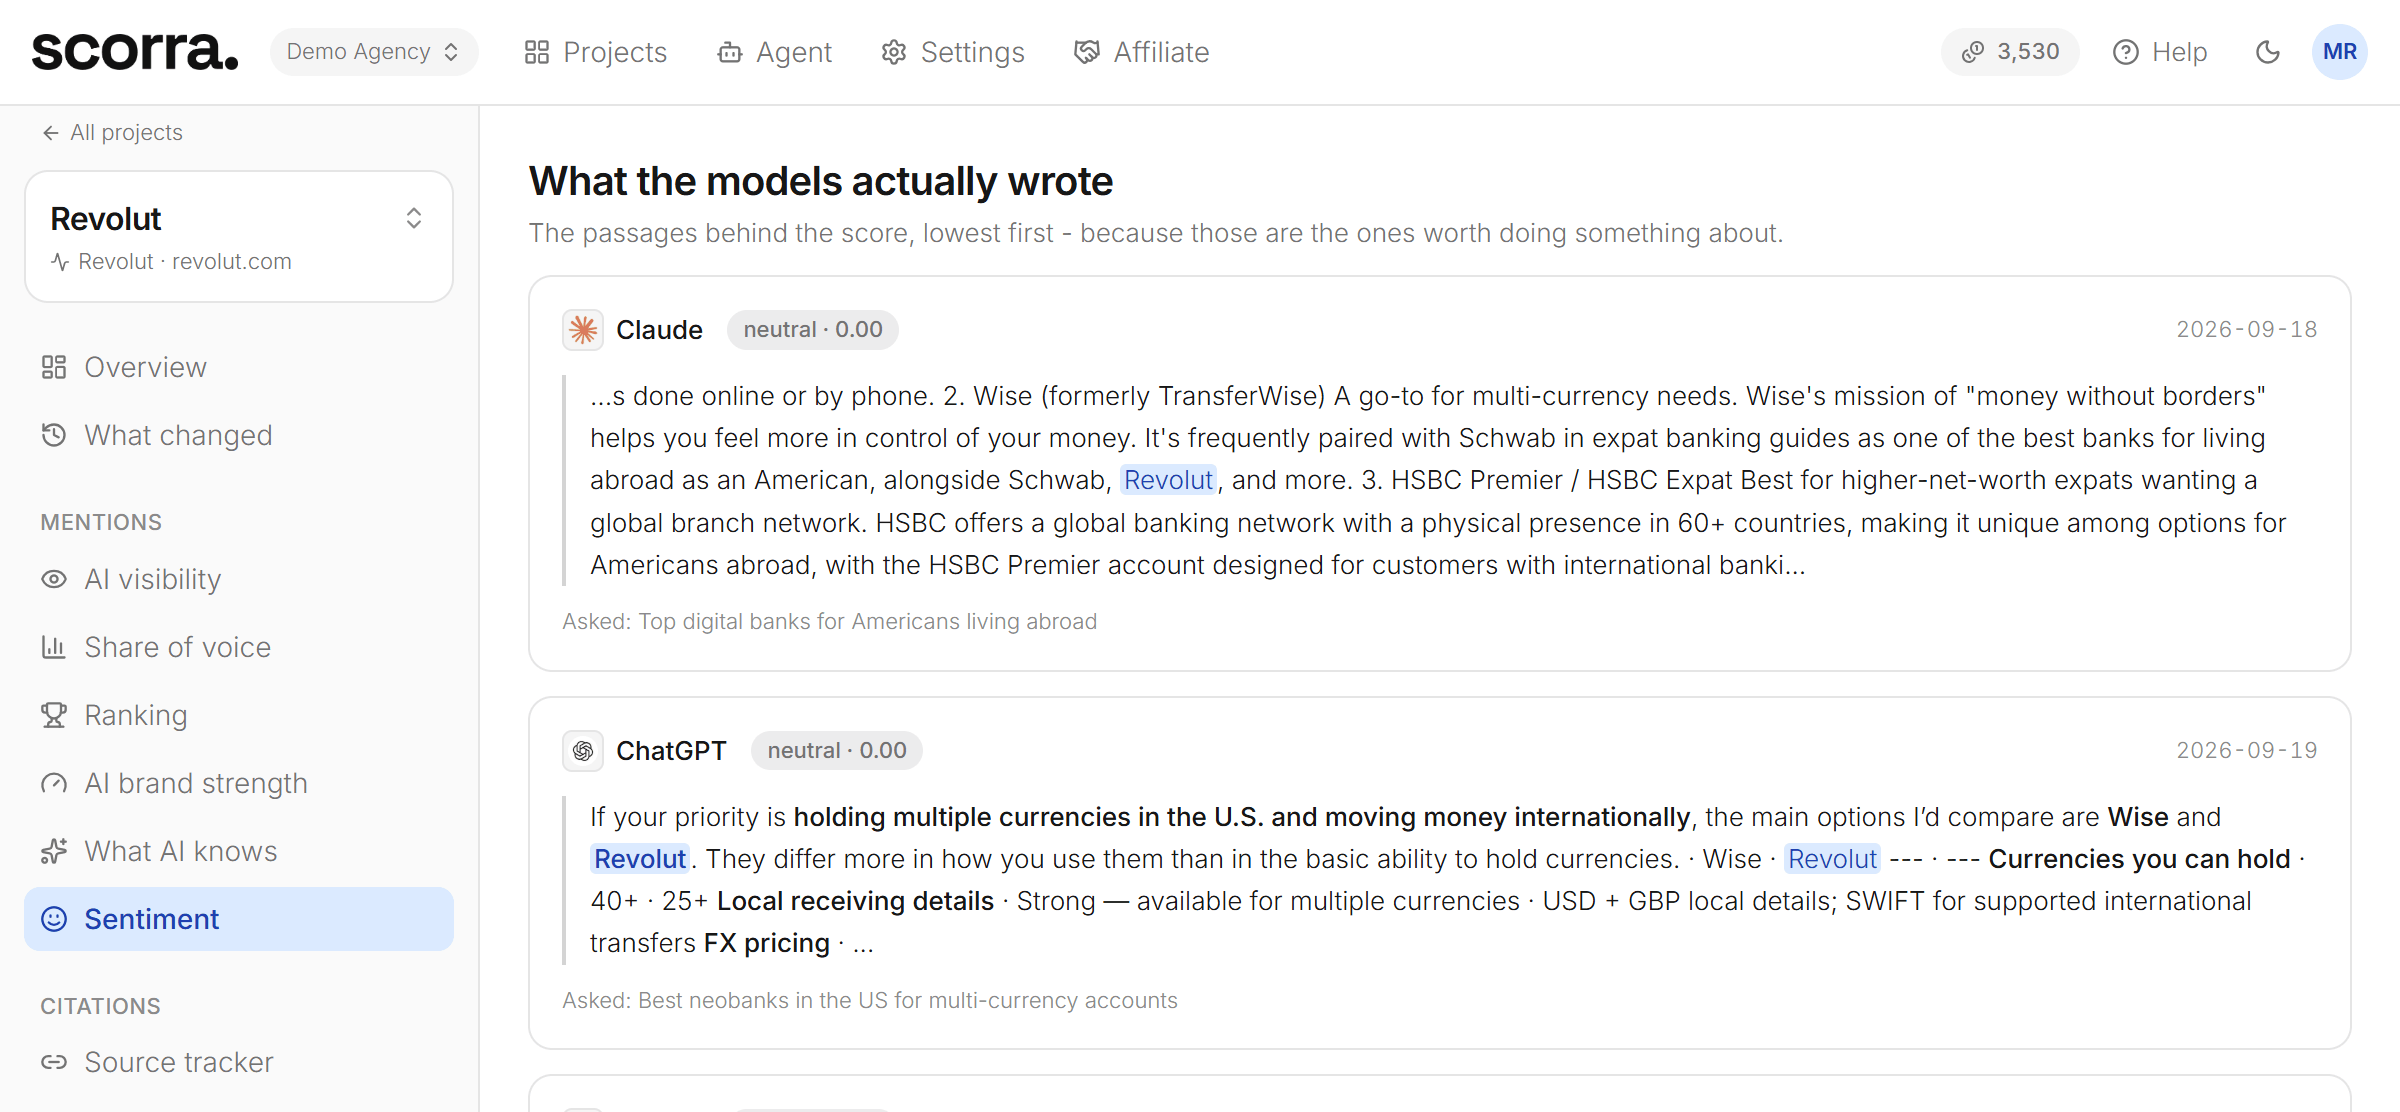
Yesterday’s answers, next to today’s
Change tracking for AI answers: which stopped naming you, which started, and which moved — each one with the two answers side by side.
What you get: A drop in visibility becomes a sentence you can act on the same week, not a number in next quarter's report.
Every other tool stops at the chart
Knowing you are invisible on four prompts is not the hard part. Writing the page that fixes it is.
Writes the page that wins the prompt
Content generation from your own data: a brief or draft built from the questions you lose, every number carrying its source. Your team edits instead of starting from a blank page.
Rewrites what holds you back
Content optimization for AI: it reads your page the way an assistant does, then returns it quotable — so pages you already paid for start earning citations.
Finds the placement worth buying
Placement and outreach opportunities: domains cited in the answers you lose, cross-checked against a rate card, so the budget goes where the assistants read.
Never publishes behind your back
Everything it writes is saved as a draft, and it runs under the credit ceiling you set — real work delegated, with control and spend staying with you.
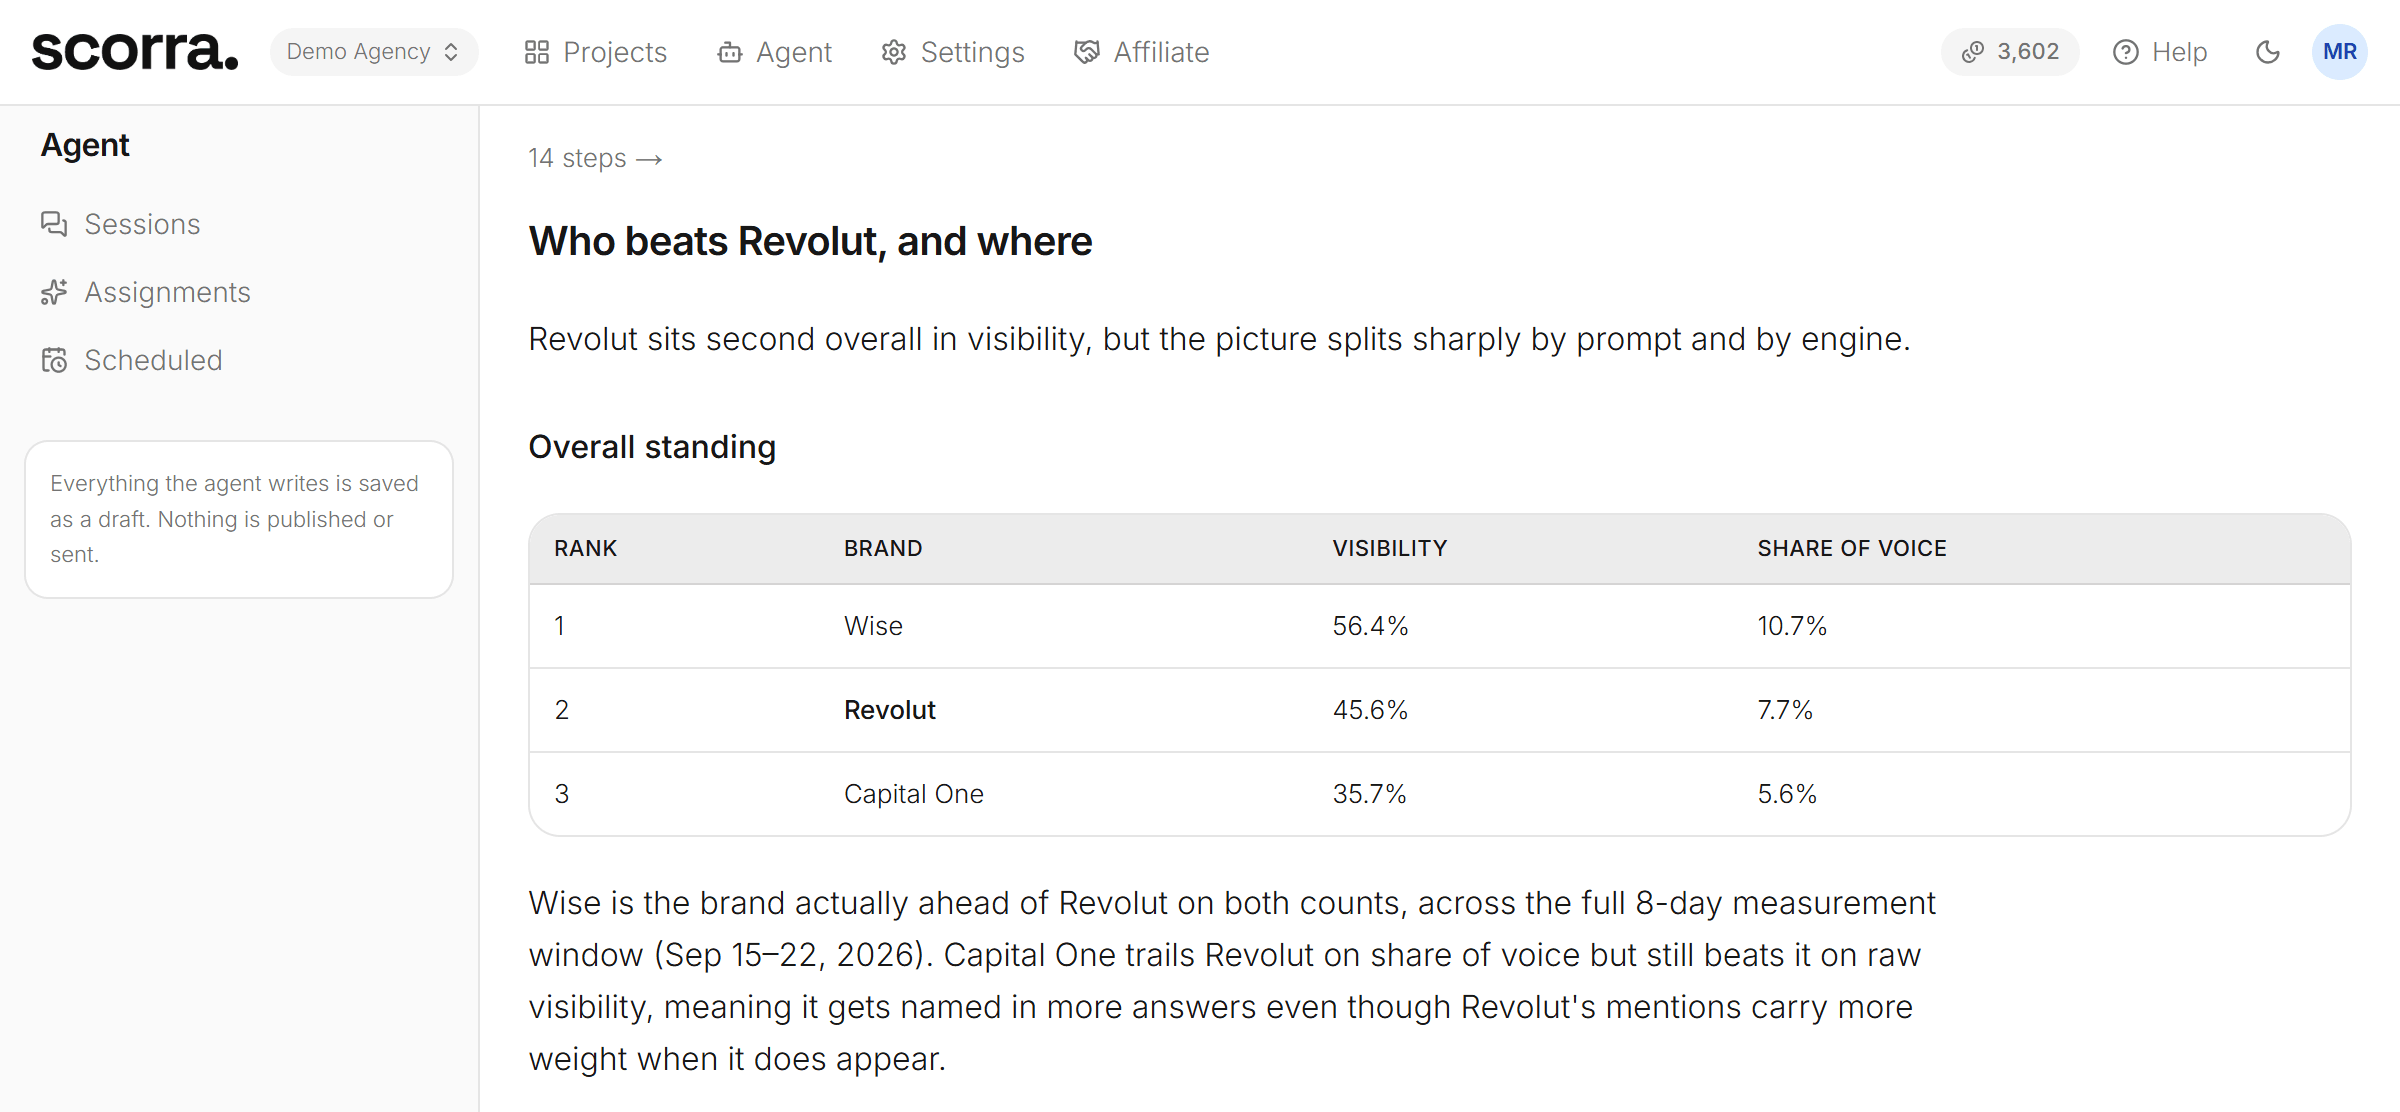
It ends with a to-do list, not a conclusion
Every session closes on named actions with the effort they cost and what it needs from you. Ask for a change in the same thread and it re-reads the data it needs.

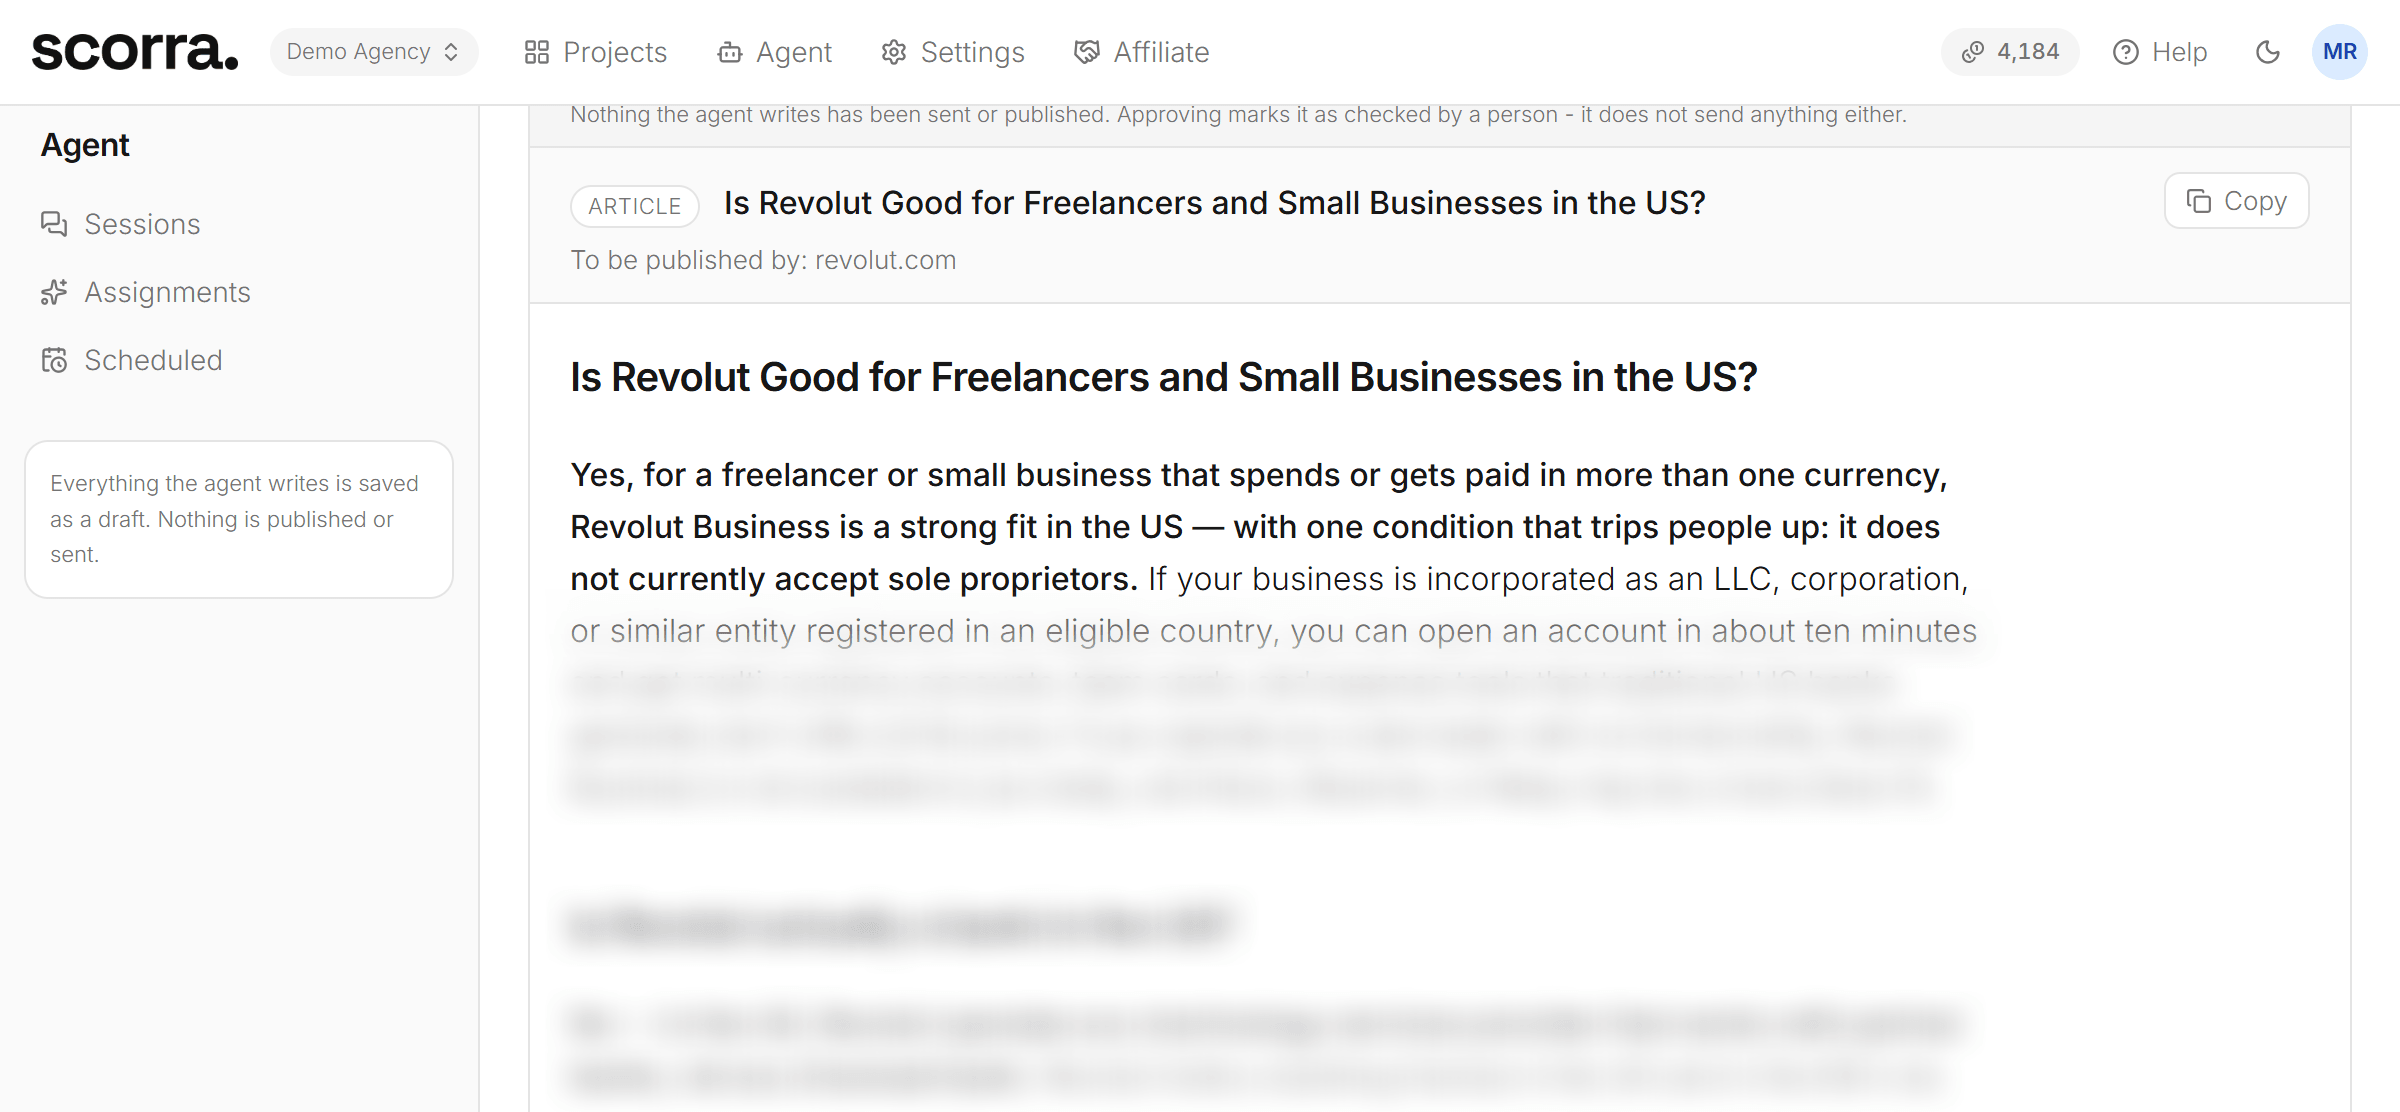
Then it writes the page
Click one row and the agent drafts it - from the numbers in the session above, not from thin air. It lands as a draft addressed to your domain, with the gaps it could not verify marked rather than invented. Nothing is published and nothing is sent.
From a tracked prompt to a published page
Add your prompts
The questions your buyers type. Paste a list, import a CSV, or let it suggest them from your site.
It measures daily
Every prompt on every assistant you picked, from the market you sell in. Failed queries never enter a metric.
See what decided it
The pages they cited and what kind of source each one is, the brands named instead of you, and the sentences behind the sentiment.
The agent does the work
It writes the page, rewrites the weak one, or finds the placement worth buying — then you publish.
One price a month
Any three of five assistants on Starter and Growth, all five on Scale and Agency — measured every day, no per-assistant add-ons. Competitor brands are never capped, and every plan comes with credits for the agent that does the work.
For one brand in one market, with the basics measured properly.
ChatGPT
Gemini
Perplexity
Google AI Mode
For a team on several markets, with the agent writing what the data shows.
For a portfolio of brands, or an agency with a handful of clients.
For an agency with 15–25 client brands – one subscription, no per-client fee.
Claude
GrokAPI
MistralAPI
What each plan covers
| Plans | Starter$75/moStart trial | Growth$195/moStart trial | Scale$599/moStart trial | Agency$999/moStart trial | CustomCustom pricingTalk to us |
|---|---|---|---|---|---|
| Tracked prompts | 40 | 120 | 300 | 600 | Custom |
| Assistants | 3 / 5 | 3 / 5 | 5 | 5 | Custom |
| Tracking frequency | Every day | Every day | Every day | Every day | Custom |
| AI answers a monthPrompts x assistants x 30 days | 3,600 | 10,800 | 45,000 | 90,000 | Custom |
| Agent credits a month | 1,000 | 4,000 | 9,500 | 15,000 | Custom |
| Site crawls and auditsPer project, per calendar month | 2 each | 2 each | 2 each | 2 each | Custom |
| Projects | 1 | 3 | 10 | 30 | Custom |
| Seats | 3 | 5 | 15 | Unlimited | Custom |
| History | 90 days | 365 days | Full | Full | Custom |
| MCP and API | – | Custom | |||
| Client accounts | – | – | – | Custom |
Compare every plan, feature by feature
Prices exclude VAT and sales tax. Paddle adds it at checkout where it applies.
Before you ask
What data analytics does Scorra include?
Visibility (AI mention rate), share of voice, position distribution (AI rank tracking), sentiment analysis with the sentences behind it, and a brand strength score, by day, assistant, topic and market. Citation analytics (source tracking) by domain and page, with seven source categories and eight content types, the questions each source feeds, and the citation gap: sources read often in answers that never name you. A brand accuracy check of what each assistant knows about you, change tracking with the two answers side by side, query fan-out where the assistant exposes it, prompt suggestions from your own site, a GEO audit (AI readiness audit) with twenty-two checks, and a content gap map. Everything exports to CSV, and from Growth up into Looker Studio, over MCP and through the API.
How does Scorra compare with Peec AI, Profound or Otterly?
All of them measure how assistants name your brand and which sources they cite. Scorra measures every assistant your plan includes daily, with no per-assistant add-ons, and adds an agent that turns the gaps into drafts, rewrites and outreach. What it does not have: a database of real user prompt volumes, analysis of AI crawler traffic from server logs, and GA4 traffic attribution. If those decide it for you, an enterprise tool such as Profound covers them.
Is Scorra the same as scorra.io?
No. Scorra at getscorra.com is an AI visibility platform that measures how ChatGPT, Gemini, Perplexity and Google's AI answers describe a brand. scorra.io is an unrelated security scanner for apps built with AI coding tools.
How is this different from a rank tracker?
A rank tracker tells you where a page sits. This tells you whether an assistant names your brand when someone asks a buying question — and which pages it read to decide that. The two rarely agree: the pages that win AI answers are often not the ones that rank.
Which assistants do you measure?
ChatGPT, Gemini, Perplexity, Google AI Mode and Google AI Overviews, from the market you sell in. Starter and Growth measure any three of them - you pick, per project - and Scale and Agency measure all five. Every one runs every day, none of them weekly. Claude, Grok and Mistral are measured on Enterprise, where the price is agreed rather than printed on a card. AI Mode and AI Overviews are separate surfaces that answer differently, so we measure them separately.
What happens when my credits run out?
Daily measurement keeps running. Credits pay for the agent, site crawls, audits and tool calls over MCP — work you ask for. A day that was not measured cannot be measured again later, so it is not something we take away mid-month.
Does the agent invent numbers?
It cannot make them up unnoticed. Every figure it writes is either pulled from your measured data or marked as unverified, and each of its tools answers one question and returns one shape — there is no free-form query for it to improvise with.
How does the free trial work?
Seven days on all five assistants, so you can see which ones matter before you pick a plan. It starts with a card, so measurement can run without a second signup. Cancel before day 7 and nothing is charged; if you do not, the first month starts automatically.
How long until I see something?
The first run starts within minutes — a new project goes to the front of the queue — and the answer screens fill as the answers come back. Trends need a few days: one day of data is a point, not a line, and the screens say so rather than drawing one.
Can I track more than one brand or market?
Yes. A project is one brand in one market, and the plans include Starter 1, Growth 3, Scale 10, Agency 30. Competitor brands inside a project are not capped. Archive a project you no longer measure and its place is free again - the history stays.
Find out what they are saying today
Or start a 7-day trial with the same assistants your plan measures. Card required. Cancel before day 7 and nothing is charged.